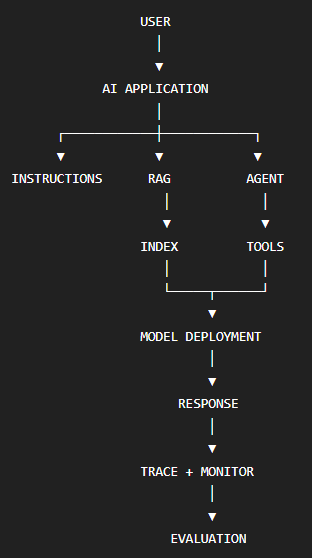
F5 - GenAI evaluation and production
-
production quality is multidimensional, so is GenAI evaluation
-
grounded-ness is the degree to which response claims are supported by available context
-
relevance is the degree to which the response matches the question
-
a representative evaluation set should be created:
Question 1
expected/reference information

Question 2
expected/reference information

...

Question N
expected/reference information
-
two application versions can be ran against the same evaluation set, and compare grounded-ness, relevance, retrieval quality, task success, latency, token use, cost
-
lineage might need:
Application release v12
│
├── model deployment/version
├── system prompt:v7
├── retrieval config:v4
├── embedding model
├── index/corpus version
├── tool definitions
└── evaluation results
-
agent evaluation should consider more than just the response quality
-
it should check for correct tool selection, correct arguments, tool execution, correct sequence, task completion, and unnecessary tool calls
-
monitor after deployment as pre-production evaluation doesn't guarantee future behaviour
-
GenAI quality can change without model changing, as application also consists of other components such as search index, tools, etc